Cybersecurity Threat Detection: A SOC Guide for 2026
Chances are you are already dealing with this. Your SIEM gathers more logs than any person could review, your endpoint tool raises alerts that seem critical until they turn out not to be, and someone in leadership keeps asking whether the organization is covered without ever saying what covered actually means.
That is the strain behind cybersecurity threat detection in 2026. Another standalone console is not what teams need. What they need is proof that the environment can be seen, that suspicious behavior is linked into incidents, and that the SOC can convert those incidents into response actions and audit evidence without assembling the same narrative three separate times.
Table of Contents
- What Cybersecurity Threat Detection Really Means
- Core Detection Techniques and When Each One Shines
- Telemetry Sources and Ingestion Pipelines
- Detection Engineering and Rule Tuning That Actually Reduces Noise
- Alert Triage, SOAR Automation, and the Metrics That Matter
- Compliance, Reporting, and Audit-Ready Evidence
- Implementation Checklist for a Unified Detection Platform
What Cybersecurity Threat Detection Really Means
A Tier 1 analyst begins a shift and notices three things that appear unrelated. An employee logs in from a new location. Minutes later, that same identity reaches a file share it seldom touches. Then a workstation starts a script interpreter from a document. No single one of those events confirms compromise. Taken together, they may point to account misuse, staging, or the early stages of data theft.
That is cybersecurity threat detection put simply. It is not merely about catching malware. It is the practice of uncovering attacker behavior across endpoint, network, identity, server, cloud, and application activity, and then converting that evidence into something a person can act on.
Today's teams encounter this magnitude on a daily basis. Microsoft's 2025 Digital Defense Report says Microsoft processes 100 trillion security signals daily, analyzes 38 million identity risk detections in an average day, and blocks 4.5 million net new malware files every day, with over 52% of cyberattacks with known motivations driven by extortion and ransomware. That is why mature programs no longer base detection solely on file signatures. They watch for identity abuse, unusual behavior, and indications of data movement.
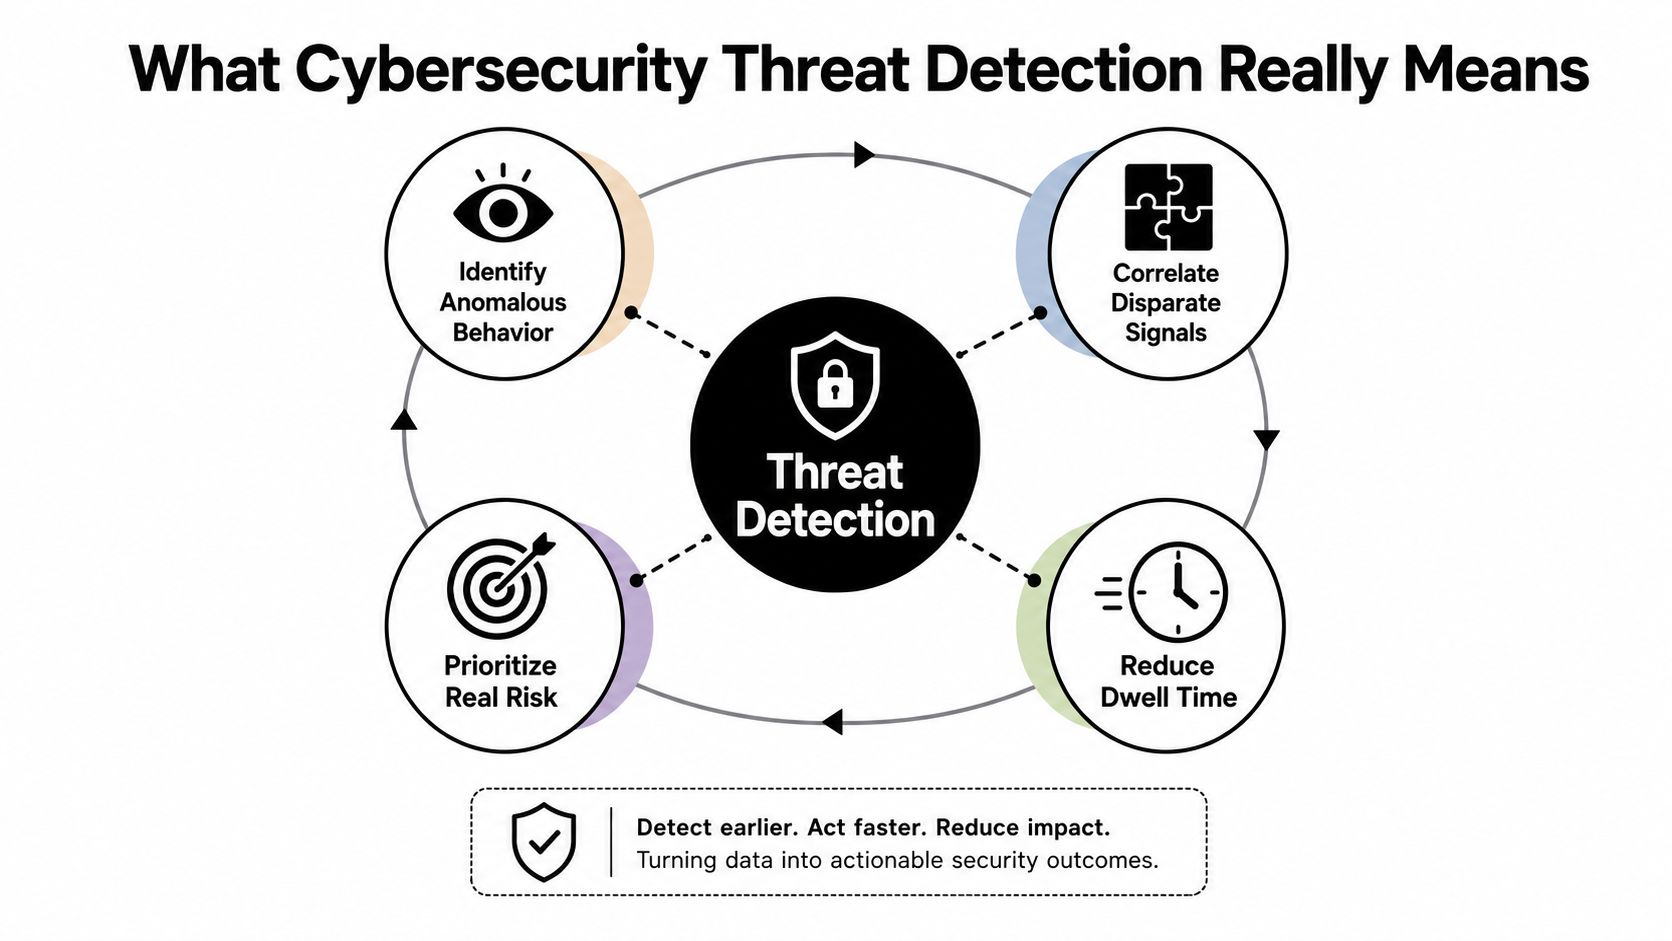
The three outcomes that matter
Good detection programs serve three practical goals:
- Reduce dwell time: Detect malicious activity before an attacker can establish a foothold and widen access.
- Limit blast radius: Bring incidents to light early enough for responders to isolate a host, disable an account, or halt follow-on actions.
- Produce evidence: Retain the raw events, correlation logic, and investigation trail that internal review and audits require.
Many readers get hung up on products at this point. They ask whether they need SIEM, EDR, XDR, SOAR, NDR, or every one of them. The more useful question is whether the SOC can gather telemetry broadly, correlate it, and deliver a single incident timeline rather than scattered alerts. If you want a quick refresher on how the team itself is structured, this overview of a SOC in cybersecurity is useful context.
Practical rule: A detection that reports only that something occurred generates workload. One that unites identity, process, and network evidence into a single incident generates decisions.
For smaller regional teams, that design challenge is not theoretical. A local guide on threat detection for Indiana businesses offers a solid example of how coverage questions surface in real operating environments, particularly where lean IT teams need security visibility without a large SOC.
Core Detection Techniques and When Each One Shines
A strong SOC does not choose one detection method and assume it covers all cases. It develops coverage across multiple techniques, then correlates their output so a weak signal can be validated against another.
This is significant since the volume is neither low nor consistent. Fortinet's 2025 Global Threat Analysis shows detections reaching 1.16 trillion in 2025 versus 993 billion in 2024, a 16.71% year-over-year increase, with FortiGuard Labs observing about 36,000 scans per second across the globe. At that rate, a SOC requires layered detection that separates ordinary background noise from chains of behavior worth investigating.
Signature detection
Signature rules are the most precise instrument for known-bad activity. They perform well when the pattern is already understood and the artifact remains stable.
A few examples:
- A malware hash that matches a known family
- A command line pattern tied to a common downloader
- A network IDS rule that matches a well-understood exploit attempt
Precision is the benefit. The trade-off is straightforward. If an attacker alters the file, command, or packet shape, the signature can miss it. Signature logic performs best against repeatable threats and less well when the adversary can change surface details while keeping the intent the same.
Anomaly and behavioral detection
Behavioral detection asks whether an action stands out as unusual for a user, host, service account, or workload. It proves most valuable when the artifact itself appears normal while the sequence around it does not.
One common scenario involves an office document spawning PowerShell, after which the workstation establishes a network connection it does not usually initiate. In another, a successful login from an unfamiliar location is followed by mass access to files the user typically disregards. behavior anomaly detection assists the SOC in catching activity that a static blacklist would not match, particularly when the attacker relies on legitimate tools or valid credentials.
Signatures answer “have we seen this exact thing before?” Behavioral analytics answer “does this action fit what this asset or identity usually does?”
Noise is the trade-off. Behavioral rules can be sensitive to business change, travel, patching, or new automation, so the SOC must tune baselines carefully and keep watching for false positives.
Endpoint-focused detection
EDR and XDR telemetry supplies analysts with process tree data, parent-child links, file writes, registry modifications, service creation, and script execution specifics that ordinary logs frequently overlook.
That level of detail counts once an attacker establishes a foothold. When a legitimate admin tool is used for lateral movement, endpoint telemetry can reveal the process that spawned it, the token context, and the persistence action that came afterward. A firewall log by itself generally cannot. Endpoint data also helps teams explain investigations later, since responders can show what ran, what changed, and what started next within a single incident view.
Threat intelligence matching
Threat intelligence brings external context to activity inside the environment. Valuable indicators include file hashes, malicious IPs, domains, registry keys, and packet-level information. On its own, intelligence matching may generate noise, as many indicators expire quickly or appear in legitimate traffic. When paired with endpoint or identity signals, it becomes actionable.
A practical mental model looks like this:
| Detection style | Best at catching | Common weakness |
|---|---|---|
| Signature | Known malware and repeatable patterns | Novel or modified threats |
| Behavioral | Suspicious use of legitimate tools | Drift and false positives |
| Endpoint telemetry | Deep host-level execution context | Gaps if agents are missing |
| Threat intelligence | Known-bad infrastructure and artifacts | Short-lived indicators and context-free hits |
The error lies in seeing these as rival approaches. An effective SOC combines them within a single workflow, keeping alerts, investigative evidence, and response actions linked. A signature detects commodity malware. A behavioral rule detects a login that does not match. The endpoint trace reveals what started. The intelligence feed indicates whether the destination has a malicious past. When those signals arrive in one platform, SIEM, XDR, SOAR, and compliance evidence can support a single incident path rather than separate queues.
Telemetry Sources and Ingestion Pipelines
Detection quality begins before any rule executes. If the SOC cannot gather and normalize the necessary evidence, correlation will not rescue it afterward.
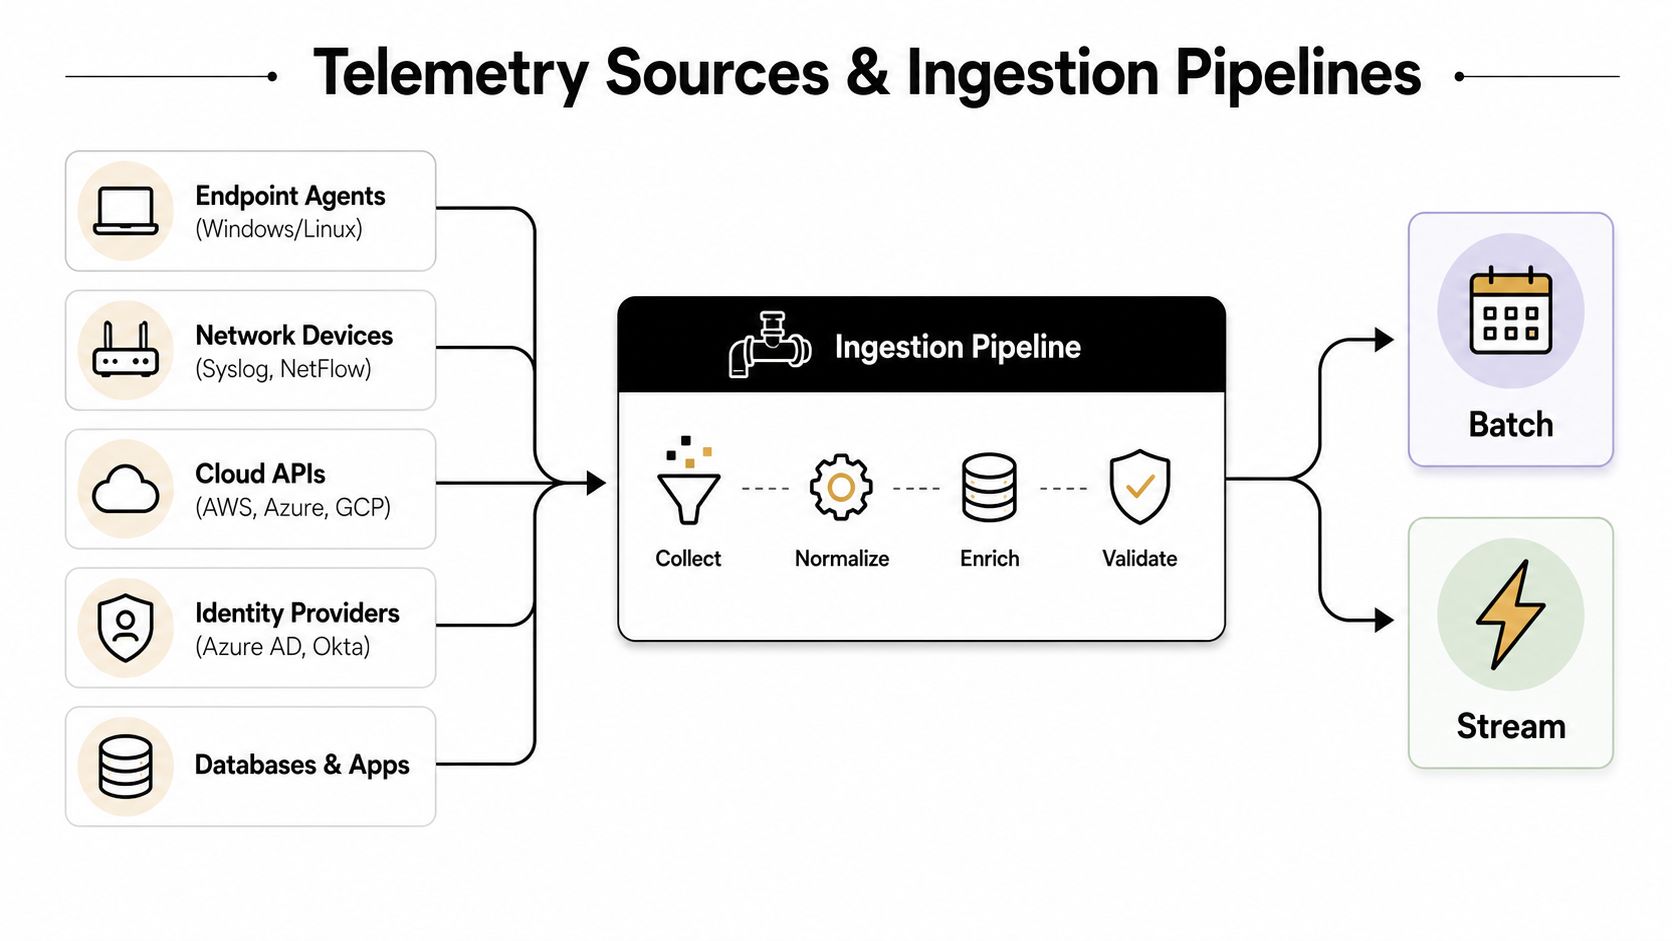
The raw material usually comes from several places at once:
- Endpoint agents: Process execution, file modifications, persistence changes, local privilege activity
- Network devices: Syslog, flow data, connection metadata, proxy events
- Identity providers: Authentication events, MFA challenges, group changes, risky sign-ins
- Cloud APIs: Control-plane activity, workload events, storage access, configuration changes
- Applications and databases: Access logs, administrative actions, unusual data reads, failed requests
Teams often underestimate the amount of engineering required between having logs and being able to detect. A collector must parse varied log formats, standardize field names, retain timestamps, and add context such as hostname, user, business owner, or asset criticality. That is the purpose of centralized log management. It provides the SOC with a single location to ingest, transform, and retain evidence before correlation logic attempts to interpret it.
Where blind spots usually appear
A 2022 IEEE review of enterprise monitoring blind spots found seven recurring gaps: encryption, cloud, data volume, shadow IT, scattered identities, multihomed devices, and nonenterprise IT. These are common failure points in actual deployments.
Here's how they show up operationally:
- Encryption: Security devices may observe connections yet not always the content, which makes endpoint and identity context increasingly important.
- Shadow IT: A team launches a SaaS app or cloud asset without following the standard onboarding process, and the SOC never receives the logs.
- Scattered identities: Users sign in through various directories and cloud services, yet the events never arrive in a single timeline.
- Nonenterprise IT: Contractors, unmanaged devices, or ancillary systems connect to core apps but do not send consistent telemetry.
A short walkthrough helps make the pipeline concrete:
Agent versus agentless is a coverage trade-off
Agent-based collection typically provides deeper host visibility. Agentless methods are simpler to deploy for cloud APIs, network appliances, and third-party services. Most mature pipelines rely on both.
When an asset cannot generate usable logs, the SOC does not yet have a detection issue. It has a visibility issue.
Detections based on one signal fall short because modern intrusions span multiple systems. A sign-in event, a process launch, and a storage access call can each appear normal on their own. Correlated on one timeline, they reveal a much different narrative.
Detection Engineering and Rule Tuning That Actually Reduces Noise
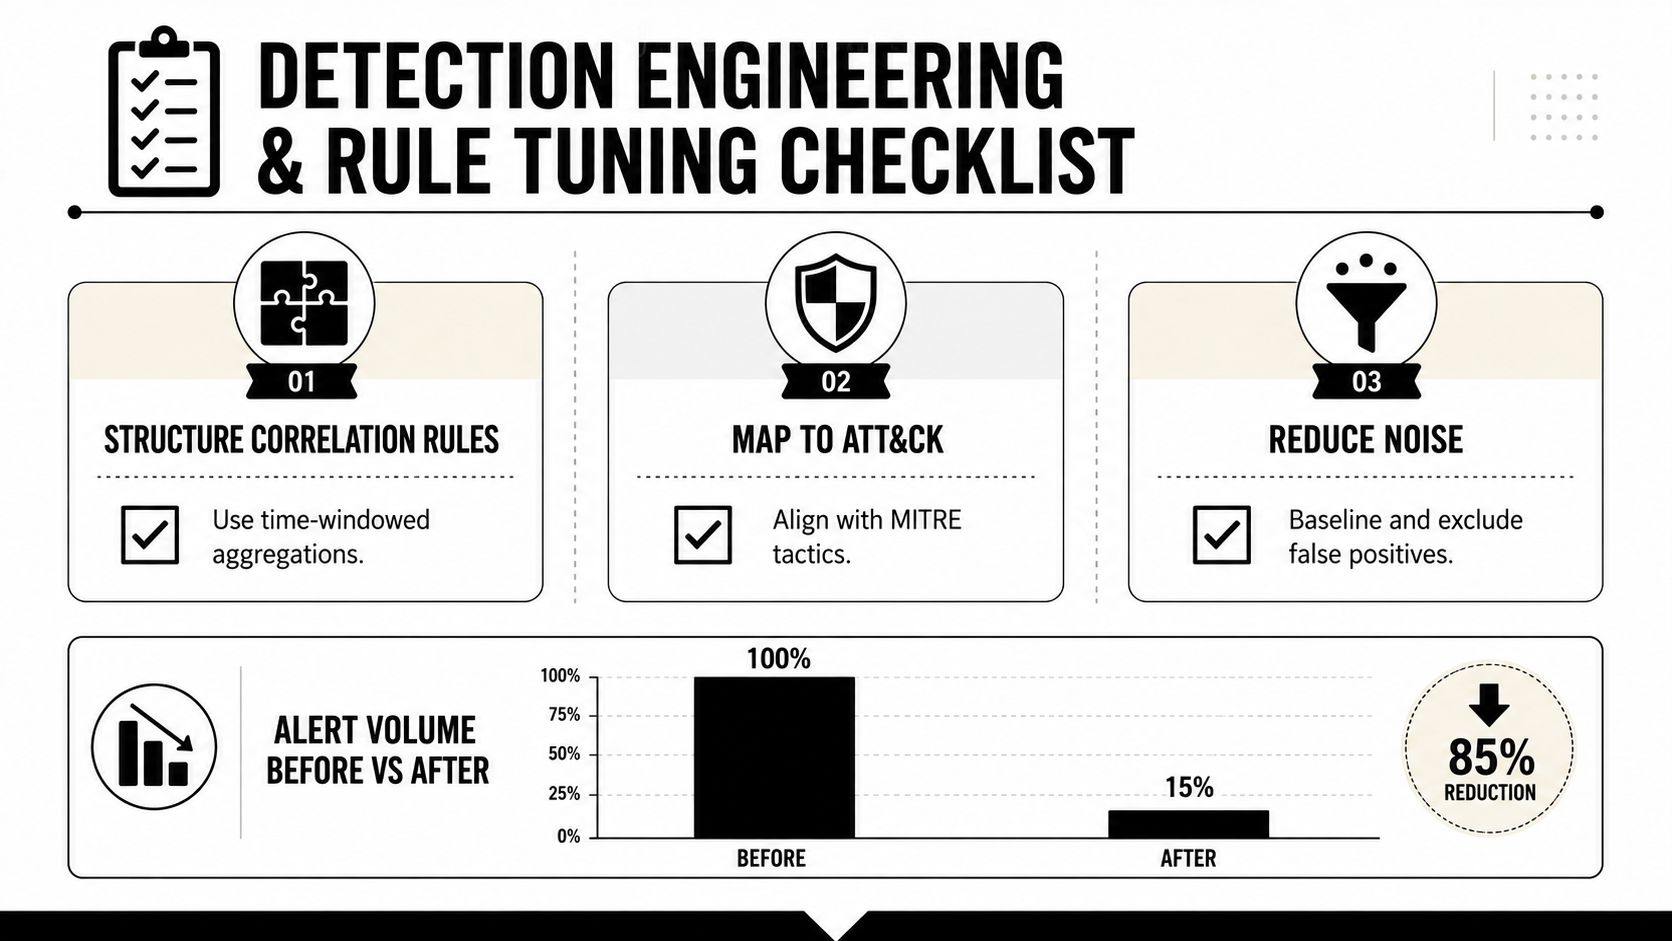
A SOC does not become calmer by adding more rules. It becomes calmer by writing rules that align with attacker behavior, add context, and reduce noise without concealing risk.
The foundation for that work is observable behavior. The most valuable detections are not arbitrary sets of conditions. They correspond to adversary techniques that defenders can observe in logs. Research about CISA and MITRE ATT&CK stresses that detection performs best when analytics align with observable adversary techniques, which can be used to prioritize detections and close visibility gaps through ATT&CK-based logic.
What a correlation rule should actually do
A useful rule answers four questions:
- What behavior matters
- On which assets or identities
- Within what time window
- With what context attached
Consider a basic example. A suspicious process begins on a workstation. Soon afterward, that host sends an atypical outbound DNS query. The same host then sets up a new service. Any one of these on its own might occur during routine administration. In combination, they merit analyst review.
That is why the depth of correlation matters more than the raw number of rules.
Tuning methods that work in practice
A noisy detection set usually improves through a few disciplined changes:
- Suppress known-good activity: Filter out approved software deployment tools, maintenance windows, and admin workflows that are well understood.
- Tune by baseline: Evaluate a user or host against its own recent behavior rather than a generic global threshold.
- Use parent-child logic: Let a single event generate a low-severity signal, and escalate only once a follow-up action is observed.
- Enrich before alerting: Before a case reaches an analyst, include the user role, asset criticality, business unit, and recent related alerts.
One industry KPI reference on security metrics defines MTTD as the average time from compromise to detection and flags an alert fatigue ratio above 60% As an indication that analysts are overwhelmed and could overlook genuine threats. That is the operational fallout of inadequate tuning. Analysts lose confidence in the queue.
Why smaller detection sets often perform better
It is tempting to boast about how many rules a platform contains. That typically misses the point. A smaller collection of high-confidence detections, mapped to key ATT&CK techniques and evaluated against actual alert outcomes, usually performs better than an enormous library no one maintains.
Field advice: Tune based on incidents, not appearance. If a rule does not help an analyst reach a decision faster, revise it or remove it.
Large language models can assist in this area, but only in a supporting role. They help summarize related alerts, suggest rule improvements, or let analysts compare noisy versions of the same pattern. Human review is still required, particularly if the rule could suppress something significant.
Alert Triage, SOAR Automation, and the Metrics That Matter
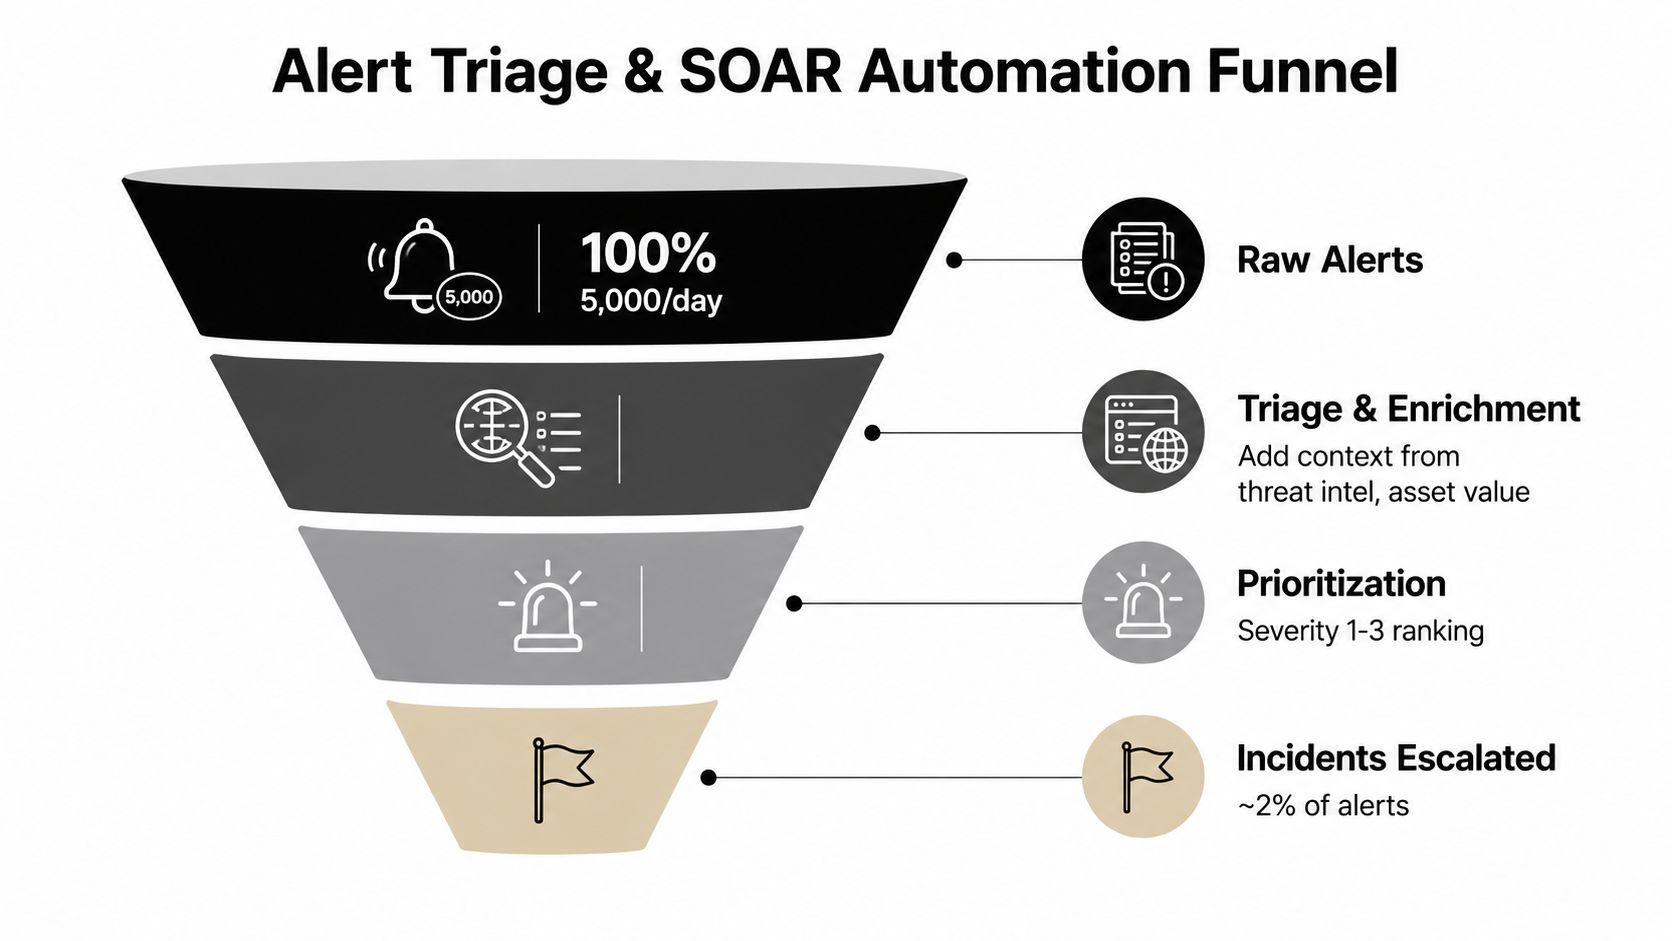
Detection turns into actual work as soon as an alert enters the queue. At that point, the SOC must rapidly answer three questions: Is it believable, how severe is it, and what comes next?
Triage is context assembly
Analysts seldom make a decision based only on the raw alert. They require enrichment around it:
- Identity context: Is this a privileged account, a service account, a contractor, or a standard employee user?
- Asset context: Is the host a developer laptop, a domain controller, a finance server, or a lab machine?
- Threat context: Do related indicators show up elsewhere in the environment, and has the same pattern triggered recently?
- Business context: Would isolation disrupt clinical operations, a manufacturing line, or payroll processing?
Many teams feel the strain of separate tools during that enrichment step. Endpoint details sit in one console, authentication logs in another, and cases in a third. A unified workflow matters because analysts should not have to rebuild the timeline manually.
SOAR should automate repetition, not judgment
Effective SOAR playbooks do not take the place of the SOC. They eliminate the repetitive steps that consume time.
Common playbooks include:
- Host containment: Isolate a device after a high-confidence endpoint detection
- Account actions: Disable or challenge an account after suspicious sign-in and privilege change activity
- Evidence collection: Pull related logs, endpoint artifacts, and case metadata into one investigation record
- Notification routing: Open the right ticket and notify the asset owner or on-call responder
The boundary is straightforward. Machines manage repeatable execution. People manage ambiguity, business impact, and exceptions.
A mature SOC does not automate because automation sounds sophisticated. It automates because analysts should not spend their most valuable time moving evidence between screens.
The metrics worth watching
Operational metrics should show whether the system helps defenders act faster and overlook fewer threats.
A practical set includes:
- MTTD: How long compromise sits before the SOC detects it
- MTTR: How long the team takes to contain or remediate after detection
- Alert fatigue: Whether the queue is drowning analysts in low-value work
- Escalation quality: Whether the incidents reaching upper tiers contain enough evidence to act immediately
The point is to measure the entire loop, not merely alert volume. A platform that generates more alerts without improved triage, automation, and case evidence adds work, not resilience.
Compliance, Reporting, and Audit-Ready Evidence
Security teams frequently view compliance as a separate track. In practice, the same detection pipeline that helps the SOC investigate incidents also enables the organization to demonstrate control operation during audits.
Compliance-focused detection guidance makes that point directly: HIPAA, PCI, GLBA, CMMC, ISO 27001, and SOC 2 Rely on evidence collection, access monitoring, and log retention workflows to demonstrate detection, investigation, and response activity in audits.
What that means day to day
A compliance-aware detection program translates framework language into concrete evidence streams:
| Framework area | Detection evidence the SOC should retain |
|---|---|
| Access monitoring | Failed logins, privilege changes, risky authentication patterns |
| Administrative activity | Actions by privileged users, service account use, policy changes |
| File and data activity | Sensitive file access, unusual reads, transfer events, integrity checks |
| Incident handling | Case history, analyst notes, timeline of actions, containment records |
| Log retention | Raw events, normalized logs, search history, rule outcomes |
Numerous organizations encounter difficulty. They may possess a SIEM that produces alerts, yet they cannot readily demonstrate which control a detection maps to, what evidence was examined, or how the investigation ended.
Compliance-blind detection creates rework
If the SOC functions separately from compliance, the same event gets handled three times. An analyst examines it. Later, a compliance officer asks for evidence. An auditor then requests retention and case records in yet another format.
A stronger approach connects detections to control objectives from the start. Monitoring failed logins supports access controls. Auditing privileged accounts supports governance requirements. Monitoring file activity supports integrity and data protection controls.
This shifts the role of the SOC. It becomes not only a detection center but also an evidence-generating function that the business can defend before auditors, customers, and regulators.
Implementation Checklist for a Unified Detection Platform
If you are building or rebuilding a detection program, begin with workflow design, not product logos. Order matters more than the marketing label.
Build the collection layer first
Bring evidence into a single location before you attempt to perfect analytics.
- Deploy collectors and agents: Include endpoints, network devices, identity systems, cloud services, and critical applications.
- Normalize fields early: Normalize usernames, hostnames, timestamps, event categories, and severity tags.
- Tag business context: Where possible, attach owner, department, criticality, and compliance scope to each source.
If you skip this step, tuning every later detection becomes more difficult.
Then build correlation around risk paths
Begin with the behaviors you most need to catch. Credential misuse, suspicious execution, privilege abuse, lateral movement, persistence, and unusual data access usually offer greater value than importing a massive generic content pack.
A practical rollout often looks like this:
- Map priority detections to ATT&CK: Concentrate on techniques that matter to your environment and threat model.
- Integrate threat intelligence: Treat it as context, not as your sole detection logic.
- Create response playbooks: Automate the first actions for the most common incidents with the highest confidence.
- Wire evidence to compliance controls: Ensure every key detection can support an audit narrative later.
Collapse the workflow where it makes sense
A unified platform can assist. Rather than stitching together separate SIEM, XDR, and SOAR products, some teams use a single stack that collects logs, correlates events, executes playbooks, and keeps case evidence in one place. Unified Security Stack represents one example in that category. It brings together open-source SIEM, SOAR, and XDR It provides log management, vulnerability scanning, access rights auditing, endpoint protection, file tracking, and compliance workflows for frameworks including CMMC, HIPAA, SOC 2, ISO 27001, PCI, GDPR, and GLBA.
This matters because detection design is truly a workflow problem. If telemetry, correlation, case handling, and audit evidence sit in separate systems, the SOC wastes time on handoffs. If they sit in one operational path, the team can move from signal to incident to response without rebuilding context.
Select the architecture that helps analysts answer one question quickly: what happened, how certain are we, and what action should we take now?
A practical readiness checklist
Before you call the program mature, verify these points:
- Coverage is measurable: You are aware of which assets, identities, cloud services, and apps produce logs you can use.
- Rules are engineered: Detections are linked to behaviors and evaluated against outcomes.
- Triage is enriched: Within one case, analysts can view identity, asset, and threat context.
- Automation is targeted: Scripting handles repetitive response steps, but human decisions remain human.
- Compliance is built in: The system keeps the proof required to demonstrate monitoring and response actions.
Much of the confusion surrounding cybersecurity threat detection fades when you no longer view it as an exercise in buying tools. It is a discipline of coverage and correlation. Tools matter. Workflow matters more.
Unified Security Stack provides security teams with a single place to gather logs, correlate endpoint, network, cloud, and identity activity, automate response playbooks, and retain the evidence required for HIPAA, PCI, CMMC, ISO 27001, GLBA, and SOC 2 workflows. If you are aiming to reduce noise while unifying SIEM, XDR, and SOAR operations, visit Unified Security Stack and assess whether an approach based on a single stack aligns with your SOC design.