Mastering Threat Hunting Techniques in 2026
Your SIEM is generating alerts, your EDR is stopping known malware, and your team is still posing the difficult question that matters most. What did we overlook? That question explains why mature security programs invest in threat hunting rather than depending solely on alerts, signatures, and prebuilt detections.
Threat hunting delivers the most value when it is treated as an operational discipline, not a heroic effort led by a single senior analyst on a Friday afternoon. The best teams begin with a hypothesis, gather the right telemetry, test that hypothesis using focused queries, and then turn what they learn into lasting detections and response playbooks. This is even more important now because living off the land has become the most common technique employed by nation-state threats, with 76% of organizations observing those behaviors in nation-state attacks during 2025, according to the Intel 471 summary of the SANS 2025 Threat Hunting Survey.
The market momentum behind hunting mirrors that operational shift. Fortune Business Insights forecasts the global threat hunting market to hit USD 14.16 billion by 2034, growing at a CAGR of 15.14% from 2026 to 2034, following a 2025 value of USD 3.98 billion and expected growth to USD 4.58 billion in 2026, as noted in its threat hunting market forecast. Yet budget growth by itself will not make hunts effective. Effective hunts come from repeatable methods, clean telemetry, disciplined tuning, and rapid translation from hypothesis to action.
This guide covers threat hunting techniques that SOC teams can execute. Each technique features a practical hypothesis, the required telemetry, sample queries, automation concepts, and tuning guidance for SIEM, XDR, and SOAR workflows in hybrid environments.
Table of Contents
- 1. User Entity Behavior Analytics (UEBA) and Behavioral Analytics
- 2. Integrating Threat Intelligence and Correlating IOCs
- 3. Detecting Anomalies through Log Pattern Analysis
- 4. Hunting with the MITRE ATT&CK Framework and Tactic Mapping
- 5. DNS NetFlow Hunting and Network Traffic Analysis (NTA)
- 6. Registry Monitoring and File Integrity Monitoring (FIM)
- 7. Command-Line Analysis and Process Execution
- 8. Hunting Credential Access and Authentication Anomalies
- 9. DLP-Based Hunting and Data Exfiltration Detection
- 10. Vulnerability Assessment, Patch Gap, and EDR Hunting for Malware
- 10-Point Threat Hunting Techniques Comparison
- Operationalize Your Threat Hunting Program with a Unified Platform
1. User Entity Behavior Analytics (UEBA) and Behavioral Analytics
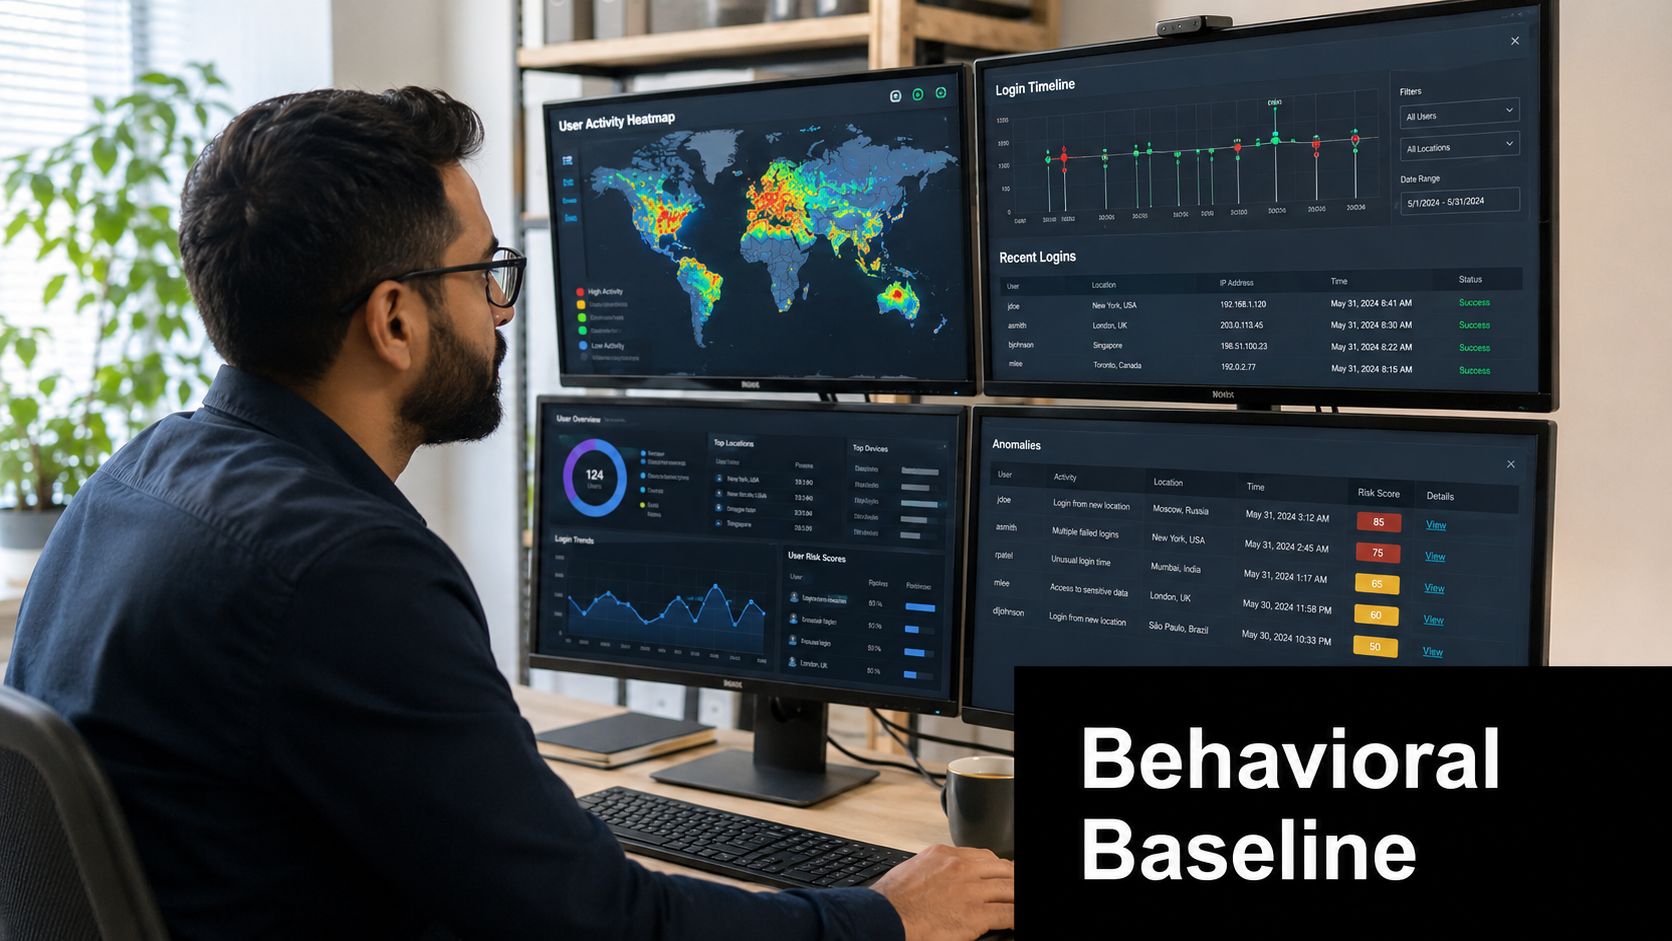
UEBA is where many teams at last begin to see attacks that signature logic overlooks. Rather than asking if a file hash is known-bad, you ask if a user, service account, host, or admin session is behaving outside its normal pattern. That is how you catch compromised identities, insider misuse, and low-noise lateral movement.
A practical hunting hypothesis appears as follows: a privileged user or service account is reaching systems, data, or admin tools in a manner that does not match its established role. In real environments, this often shows up as an administrator accessing file shares they never use, a service account suddenly authenticating interactively, or an employee downloading sensitive data at an odd time from a new device.
Build the Hunt Around Risky Behavior
Gather identity provider logs, Active Directory events, VPN activity, cloud IAM telemetry, endpoint process data, and file access events. If you are working with a platform that behavior anomaly detection, start by building profiles by role. That is typically more stable than creating one baseline per individual because people constantly change projects, schedules, and devices.
Example queries should focus on first-time or rare activity:
- Rare admin access: Locate privileged accounts connecting to servers or shares they have not accessed during the established baseline period.
- Service account misuse: Look for service accounts that have interactive logons, remote desktop use, or command-shell execution.
- Lateral movement clues: Detect a single account authenticating across multiple hosts in a brief sequence, particularly when that account normally remains scoped to one application or server tier.
Practical rule: UEBA succeeds when analysts tune for context, not just novelty. Rare activity is not automatically malicious.
Within SOAR, build playbooks that add manager, department, asset criticality, past alerts, MFA status, and recent password changes to the user context. When risk is high, initiate step-up authentication, revoke the session token, or isolate the endpoint associated with the anomaly. Tuning matters more than model sophistication. Begin with a conservative approach, keep human users distinct from service accounts, and exclude known maintenance windows so hunters do not spend effort on scheduled administrative work.
2. Integrating Threat Intelligence and Correlating IOCs
IOC correlation remains valuable, but only when teams treat it as a rapid filtering method rather than a complete hunting strategy. Skilled hunters use indicators to confirm suspicion, sweep the environment, and discover related activity around the match. They do not stop once a hash matches and consider the case closed.
The working hypothesis here is straightforward. A known malicious indicator has reached your environment, and there may be neighboring hosts, identities, or communications that your automated detections did not fully connect. This is particularly helpful for phishing infrastructure, malware staging domains, suspicious URLs in email logs, and retrospective hunts after a vendor or internal team flags new indicators.
Use IOCs as a Starting Point, Not the End State
Necessary telemetry includes DNS, proxy, firewall, email gateway, EDR, web server, and endpoint file execution logs. Unified Security Stack's platform description states that it maintains over 30 billion IOC elements, which is useful for fast enrichment and broad matching across ingested data. The operational challenge is not finding indicators. It is deciding which ones deserve analyst time.
Try a hunt sequence like this:
- Inbound phishing pivot: Compare domains or URLs from recent phishing reports with email gateway logs, then pivot to endpoint browser history and identity events from users who clicked.
- Malware retrohunt: Look through past EDR and file telemetry for a previously unseen hash or domain, then examine the parent process, user context, and later network connections.
- Infrastructure correlation: Find a single suspicious IP in firewall logs, then determine every internal asset that talked to it and whether those assets have a common user, subnet, business unit, or software stack.
A useful external read on deception and executive risk is this piece on deepfakes and business strategy, particularly when you're connecting phishing and impersonation indicators to wider business exposure.
SOAR ought to enrich each hit with prevalence, first-seen, last-seen, asset criticality, and whether the indicator shows up in email, DNS, proxy, and endpoint logs together. Tuning tip: lower the priority of low-confidence feed matches unless they align with hostile behavior in your own data. Hunts based only on IOCs tend to generate noise. Hunts using IOCs plus context produce cases worth escalating.
3. Detecting Anomalies through Log Pattern Analysis
At 02:13, a payment application starts returning a new kind of authentication error. Ten minutes later, the same host sends outbound DNS requests it has never sent before. No IOC matches show up. No signature fires. Log pattern analysis is designed to close exactly this kind of gap.
This hunt works when the team treats logs as evidence rather than merely something to retain. The hypothesis needs to be stated plainly: a compromised user, host, or application will generate a sequence, frequency, or combination of events that breaks its usual operating pattern before controls identify it as malicious. That puts telemetry quality inside the hunt. When timestamps drift, parsers collapse useful fields, or an important source is absent, analysts can wind up investigating ingestion failures rather than attacker activity.
The telemetry you need is wider than many teams anticipate. Bring in authentication logs, application logs, Windows and Linux system events, DNS, proxy, NetFlow, cloud audit trails, EDR metadata, and security device logs. Centralize them in a platform designed for centralized log management before you build baselines, or coverage gaps and field inconsistencies will skew the hunt.
Build the Hunt Around a Baseline and a Testable Hypothesis
A useful starting hypothesis is straightforward: systems and users show repeatable patterns by role, time window, peer group, and business cycle. Adversaries disrupt those patterns. The signal is often a rare sequence, not a single noisy event.
Examples that produce good results in production SOCs:
- Authentication spike hunt: A password spray or scripted abuse attempt will cause a brief increase in failures across many accounts, subnets, or hosts, often outside normal work hours.
- Rare destination hunt: A server or user endpoint will reach out to a domain, ASN, or geography that is unusual for its role, especially when combined with new processes or service accounts.
- Application drift hunt: A line-of-business system will produce new error codes, new log source pairings, or privilege-related events that do not match recent change activity.
A baseline that overlooks patch windows, quarter-end finance processing, backups, and developer release cycles will quickly create noise.
Example Queries and What to Look For
In Splunk, a failed-logon spike hunt can start with a time-bucketed comparison by host and user:
index=auth sourcetype=wineventlog EventCode=4625
| bin _time span=15m
| stats count dc(user) as unique_users by _time, host, src_ip
| eventstats avg(count) as avg_failures stdev(count) as stdev_failures by host
| where count > avg_failures + (3*stdev_failures)
| sort - count
The query alone is not what matters. Check whether the spike is concentrated in one account set, spread across many hosts, or linked to a single source IP range. That distinction separates a burst of mistyped passwords from broad password spraying.
In Microsoft Sentinel, KQL is useful for finding rare outbound destinations from assets that normally stay quiet:
CommonSecurityLog
| where DeviceAction == "allow"
| summarize conn_count=count() by DeviceName, DestinationHostName, bin(TimeGenerated, 1d)
| join kind=leftouter (
    CommonSecurityLog
    | where TimeGenerated between (ago(30d) .. ago(1d))
    | summarize baseline_days=dcount(bin(TimeGenerated, 1d)) by DeviceName, DestinationHostName
) on DeviceName, DestinationHostName
| where baseline_days < 3 and conn_count > 20
| sort by conn_count desc
For Elastic, rare process and command combinations often expose hands-on-keyboard activity:
FROM logs-endpoint.events.process-*
| STATS executions = COUNT(*) BY host.name, process.name, process.command_line
| WHERE executions < 3
| SORT executions ASC
These queries serve as starting points. Production hunts generally require allowlists for management servers, vulnerability scanners, backup infrastructure, software deployment tools, and known admin jump boxes.
SOAR Actions and SIEM/XDR Tuning
SOAR should handle the initial triage pass automatically. When an anomaly fires, add asset role, owner, criticality, change-ticket context, recent vulnerability scan activity, recent software deployment events, and whether the same entity also set off DNS, proxy, or EDR anomalies within the last 24 hours to the alert. If the anomaly covers multiple telemetry types, create a case. If it clearly corresponds to a planned change or batch process, close it with the supporting evidence attached.
Tuning is where this technique succeeds or fails:
- Divide baselines by asset role, department, and day type.
- Evaluate entities against peer groups rather than global averages.
- Filter out known maintenance windows and repeating batch jobs.
- Rank anomalies involving multiple signals above single-event outliers.
- Maintain a review loop with engineering teams so new applications and service accounts get baselined quickly.
The trade-off is clear. Tight thresholds catch early abuse but slow analysts down. Loose thresholds cut queue volume but miss low-and-slow activity. The right balance typically comes from tuning for sequences and context, not merely counts. A quiet database server with new external DNS behavior and failed privileged logons deserves attention even if each event stream looks minor by itself.
4. Hunting with the MITRE ATT&CK Framework and Tactic Mapping
Hunting with ATT&CK is useful because it keeps teams from chasing artifacts in isolation. Rather than asking to find suspicious PowerShell, you ask which execution, persistence, credential access, or exfiltration techniques are plausible in your environment and what telemetry would confirm or refute them. That yields far better hunts.
One practical hypothesis could be that an adversary already has initial access and is progressing into discovery or lateral movement through common techniques. Instead of listing every possible sub-technique, choose a single tactic path that fits your environment. In a Windows-heavy estate, remote service use, misuse of elevation controls, and credential access often deliver more hunting value than obscure malware families.
Start with the Technique, Then Trace the Chain
Gather evidence from endpoint telemetry, Windows security events, PowerShell logs, DNS, firewall logs, cloud control plane logs, and identity data. After that, map confirmed findings to ATT&CK IDs in your SIEM or case management workflow. This discipline matters because the 2024 SANS Threat Hunting Survey, as summarized by Hunt.io, found that 63% of organizations saw measurable improvements in security posture after implementing threat hunting, and it highlights approaches such as hypothesis-driven, indicator-based, and custom situational hunting mapped to ATT&CK in the overview of threat hunting techniques.
Good ATT&CK hunts usually follow a chain like this:
- Technique hypothesis: Look for the start of remote service sessions, questionable privilege changes, or exfiltration through unexpected channels.
- Corroboration step: Determine whether that same host also displays discovery commands, abnormal authentication paths, or archive creation.
- Containment logic: When several techniques converge on a single asset or identity, escalate right away instead of waiting for malware confirmation.
The guidance that still scales best is to hunt by behavior rather than family name.
For SOAR, tag detections with ATT&CK and allow playbooks to branch by tactic. Credential access should prompt account safeguards and memory-collection choices. Exfiltration should prompt DLP validation and network containment. Tuning tip: do not map everything at once. Begin with the techniques your team can observe with confidence.
5. DNS NetFlow Hunting and Network Traffic Analysis (NTA)
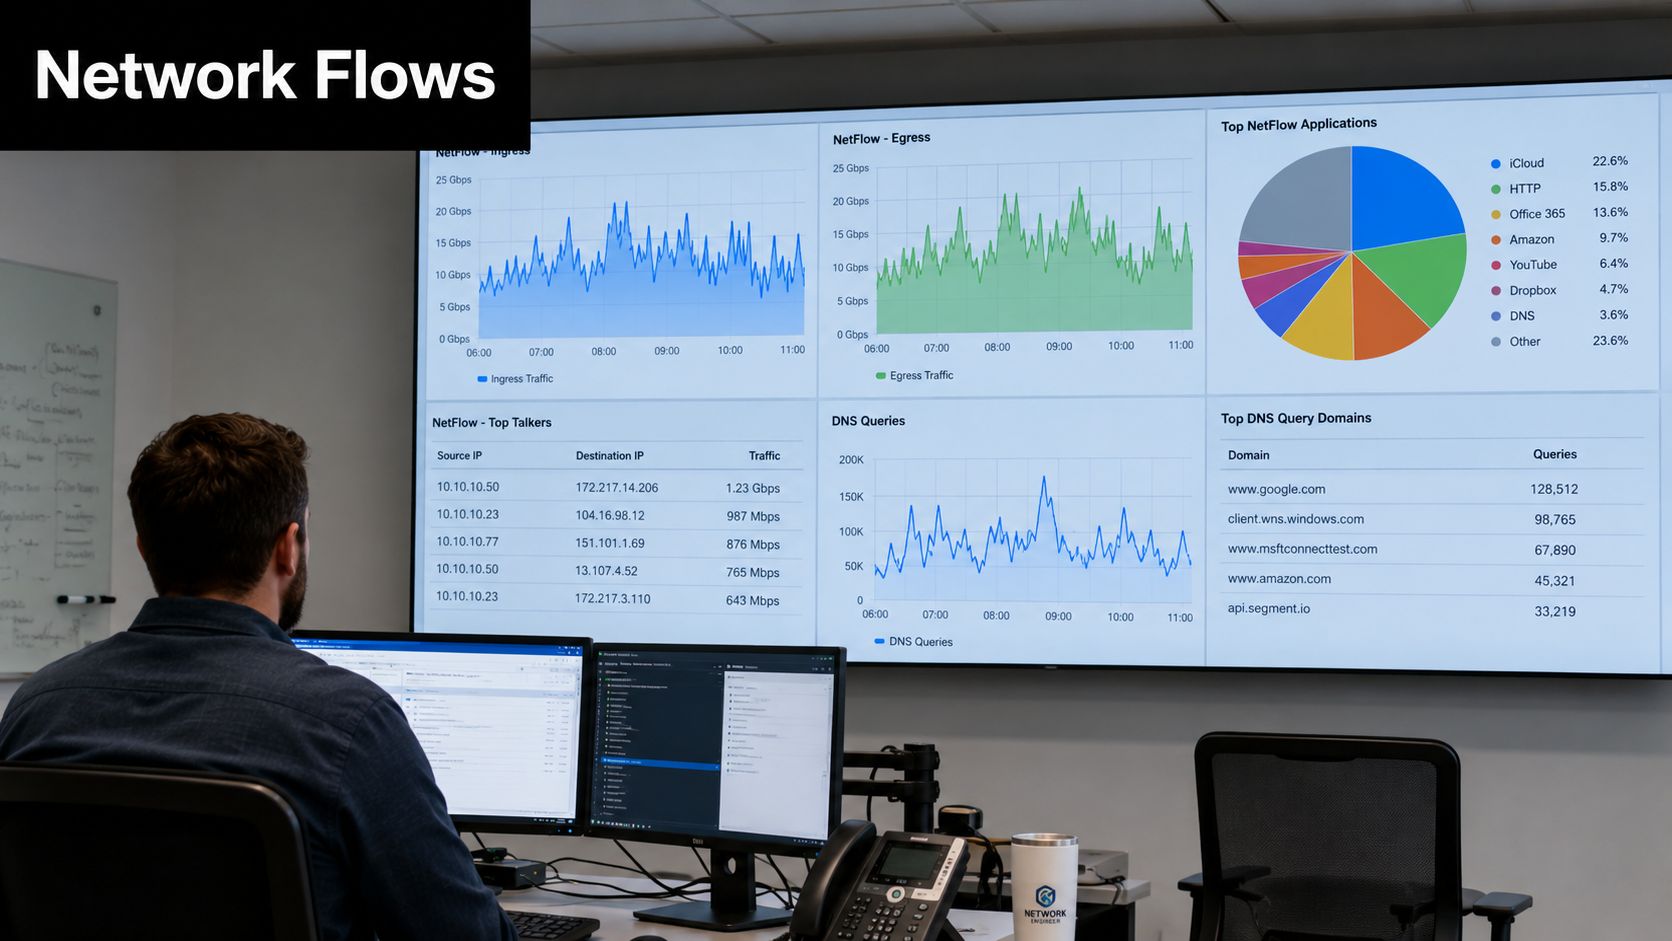
If endpoint visibility is limited, encrypted, or partly bypassed, the network often still reveals the story. Beaconing, DNS tunneling, unusual east-west traffic, long-lived outbound sessions, and odd TLS relationships commonly appear in NetFlow and DNS before an analyst sees the complete compromise on the host.
The hunting hypothesis is that a compromised or misused system is communicating in a manner that violates its expected network profile. This could be command-and-control traffic, preparation for exfiltration, peer-to-peer lateral movement, or cloud workload drift that does not match the application design.
Watch the Network When Endpoints Go Quiet
Gather NetFlow or IPFIX, firewall logs, DNS query logs, proxy logs, SSL or TLS metadata, and endpoint process-to-connection telemetry where available. If your stack supports network device monitoring, correlate flows with device role and owner before opening cases. A backup appliance and an HR laptop should never have the same egress expectations.
Use hunt queries that emphasize repetition and rarity:
- Beaconing pattern: Look for recurring outbound connections from a single host to a single destination with comparable byte counts and intervals.
- DNS abuse: Search for abnormally long query names, frequent TXT requests, or sudden spikes of requests to uncommon domains.
- Lateral movement: Detect peer-to-peer communication among workstations or cross-segment traffic that avoids expected admin jump paths.
SOAR can enrich a suspicious destination with passive DNS, earlier internal contacts, whois context, and whether any endpoint processes started the connection. It can then block the domain, isolate the host, or start packet capture on the affected segment. Tuning tip: keep allowlists for content delivery networks, software updaters, and approved remote management platforms. Without them, beacon hunts turn into a list of normal SaaS behavior.
6. Registry Monitoring and File Integrity Monitoring (FIM)
FIM is among the clearest ways to detect persistence and tampering, but only when it is narrowly focused. Teams that watch every file change on every server typically drown in noise. Teams that target startup locations, admin tools, sensitive configuration files, and privileged execution paths obtain useful results.
The hypothesis is that an attacker has modified a protected file, registry key, startup item, or permission set to establish persistence, weaken controls, or prepare for privilege escalation. On Linux, this often means changes under /etcThese include cron locations, SSH configuration, or privileged binaries. On Windows, this usually refers to registry autoruns, services, scheduled tasks, system binaries, or security-relevant configuration.
Focus on High-Value Change, Not Every Change
Necessary telemetry includes file change events, hash changes, permission changes, registry modifications, software inventory, and identity or process context showing who made the change. The most important correlation is not the file event alone. It is the change combined with the parent process, user, host criticality, and timing.
Strong hunts often include:
- Persistence checks: Look for changes to autorun keys, startup folders, scheduled tasks, service definitions, or shell extensions.
- Privilege paths: Search for changes to
sudoersPAM configuration, local group membership artifacts, or Windows security settings linked to elevation. - Binary trust drift: Detect executable substitutions in protected directories where the new hash, signer, or modification path looks suspicious.
SOAR needs to retrieve the prior and current values, the process that started the change, the file signing status, and the change ticket when available. When the change is not authorized, return the previous state if it is safe, contain the host, and create an incident while keeping the artifact intact. Tuning tip: allowlist your patch tools, package managers, and sanctioned admin scripts. Otherwise, everyday maintenance will appear malicious every day.
7. Command-Line Analysis and Process Execution
For Windows-heavy environments, my single hunting view would be process trees paired with command-line arguments. That view gives enough context for living-off-the-land activity, script abuse, defense evasion, and hands-on-keyboard tradecraft to stand out.
The premise holds that a command line or process chain can indicate attacker activity even if the binary is legitimate. A signed copy of powershell.exe, wmic.exe, rundll32.exe, mshta.exe, certutil.exe, or bitsadmin.exe is not suspicious by itself. What makes it a genuine lead is the parent process, arguments, execution directory, network follow-on, and user context.
Process Chains Expose What Static Signatures Miss
Gather Sysmon or Windows Event ID 4688, PowerShell logs, script block logs, endpoint network telemetry, file creation events, and module loads. Next, look for parent-child relationships that make no operational sense, such as Office launching command interpreters, browsers starting script engines, or remote admin tools initiated by low-privilege users.
Useful hunts include:
- Encoded script execution: Look for command lines with encoded content, odd argument lengths, or signs of obfuscation.
- LOLBin misuse: Detect known utilities run from temp directories, user profile paths, or unusual parent processes.
- Attack framework traces: Search for side effects of process injection, tools that dump credentials, or remote execution utilities such as PsExec and Impacket components.
Attackers count on many defenders continuing to alert on file names rather than execution context.
SOAR enrichment for a process can include signer details, parent lineage, recent network connections, loaded modules, and whether the same command appeared on multiple hosts. Tuning tip: create suppressions for your software deployment tools, remote support agents, and admin automation platforms. Then tighten detections everywhere else. That separation captures substantial abuse without overwhelming the SOC.
8. Hunting Credential Access and Authentication Anomalies
Identity telemetry typically provides earlier warning than malware telemetry. Attackers may change tools quickly, yet they still must authenticate, escalate privileges, pivot, and keep access. This leaves evidence in Active Directory, cloud IAM, VPN, SSO, application logs, and federation services.
The working theory is that stolen, guessed, reused, or over-privileged credentials are being used in a manner that departs from the normal pattern for the account. In enterprise environments, this often appears as password spraying, impossible travel, first-time authentication sources, MFA fatigue behavior, unusual service account use, or abrupt privilege changes.
Identity Telemetry Usually Reveals the Breach Early
The most practical data sources are domain controller logs, IdP logs, VPN records, cloud audit logs, MFA events, Kerberos events, and privileged access management records. Divide your hunts by account type. Human users, service accounts, break-glass admins, and workload identities should never share a single baseline, since their behavior is fundamentally different.
Try hypotheses such as:
- Password spray or stuffing: Search for numerous failed attempts across numerous accounts originating from a single source or a concentrated source cluster.
- Privilege misuse: Find users who log in successfully and then access systems, admin portals, or roles beyond their historical pattern.
- Cloud-native identity drift: Search for brief role assumptions, odd token use, or temporary privilege escalation in cloud environments where hosts can vanish before endpoint telemetry is retained.
That final point matters because cloud-first teams cannot depend on the same artifact-heavy method they use on laptops and servers. Concentrate on access paths, role changes, API calls, and identity context in real time.
SOAR ought to confirm that authentication originated from a managed device, a recognized ASN, an anticipated location, and an authorized access policy. When risk is high, invalidate tokens, mandate a password reset, block source IPs as warranted, and initiate a review of group memberships or role assignments. Tuning tip: keep distinct logic for service accounts. Their subtle misuse is frequent, and standard impossible-travel logic frequently overlooks them.
9. DLP-Based Hunting and Data Exfiltration Detection
Hunts for exfiltration fall short when teams search only for massive transfers. Actual exfiltration is frequently staged. Data is gathered, compressed, renamed, relocated, synced to cloud storage, or exfiltrated in smaller waves. If you alert only on a single enormous outbound event, you will overlook much theft.
The premise is that a user, host, or workload is readying or carrying out unauthorized transfer of sensitive data. This may include databases, file shares, object storage, personal cloud drives, email forwarding, removable media, or command-line archiving tools combined with outbound sessions.
Treat Exfiltration as a Sequence, Not a Single Event
Gather DLP alerts, file access logs, endpoint telemetry, proxy logs, email logs, cloud audit trails, database query logs, and removable media events. Next, correlate user role, data sensitivity, and destination type. A finance analyst exporting reports is not equivalent to a developer downloading HR records or a service account sending archives to an unapproved destination.
Good hunts usually chain events:
- Collection stage: Sensitive files are listed, copied, archived, or queried at abnormal volume.
- Staging stage: Data is relocated to temporary directories, user profile folders, cloud sync paths, or compressed archives.
- Exit stage: That same host or user starts outbound uploads, personal email messages, cloud sync, or USB writes.
SOAR playbooks ought to categorize the data at issue, alert data owners, halt the transfer when feasible, and isolate the device if the movement looks intentional and unauthorized. Tuning tip: establish baselines by user role and business process. Executives, legal teams, developers, and support staff each move data in different ways. Lacking that context, DLP hunting yields either silence or chaos.
10. Vulnerability Assessment, Patch Gap, and EDR Hunting for Malware
Exposure management and active threat hunting come together. A vulnerability scan shows where you are weak. EDR shows whether someone is attempting to exploit that weakness or has already compromised the host. The main value arises from correlating both, not running them as separate programs.
The hunting hypothesis is that a vulnerable or badly maintained asset is either exhibiting exploitation indicators or offering the quickest route for an adversary already within the environment. This holds equally for unpatched operating systems, outdated middleware, unsupported web applications, vulnerable plugins, and poorly monitored legacy systems.
Correlate Exposure with Active Behavior
The underaddressed operational issue here is converting hunts into lasting detections without generating unmanageable noise. In many mid-sized SOCs, manual hunts produce new rules that are later turned off due to weak tuning. Current guidance seldom helps teams validate those rules before deployment, particularly in open-source SIEM environments where analysts bear more of the tuning workload.
Combine vulnerability scan results, asset inventory, EDR process telemetry, memory and behavioral detections, firewall logs, web logs, and threat intel enrichment. Then ask stronger questions than whether it is vulnerable. Ask whether the vulnerable asset faces the internet, whether exploit-like behavior appears in logs, and whether that host also displays suspicious process chains, new persistence, or unusual outbound communication.
Strong hunts include:
- Exploit path correlation: Find exposed or high-value systems with known weaknesses, then review web logs, authentication logs, and EDR telemetry for signs of exploitation.
- Malware plus weakness: Locate hosts with suspicious memory behavior, injection indicators, archive creation, or ransomware-like file activity, then verify whether they had missed critical patches or were running unsupported software.
- Compensating control validation: Examine vulnerable assets that cannot yet be patched and confirm that segmentation, application control, monitoring depth, and SOAR containment actions are present.
SOAR ought to enrich cases with owner, patch status, business criticality, known controls, and the closest response option, such as isolation, blocking, or emergency change creation. Tuning tip: prioritize detections involving vulnerable assets that are externally reachable, contain sensitive data, or show attack-chain evidence in more than one telemetry source. That is how you keep EDR and vulnerability hunting centered on risk rather than volume.
10-Point Threat Hunting Techniques Comparison
| Technique | Implementation Complexity 🔄 | Resource Requirements ⚡ | Expected Outcomes 📊⭐ | Ideal Use Cases 💡 | Key Advantages ⭐ |
|---|---|---|---|---|---|
| Behavioral Analytics and User Entity Behavior Analytics (UEBA) | High 🔄🔄🔄, ML baselines, integration effort | High ⚡⚡⚡, large historical data, compute, storage | Strong anomaly detection; reduced insider dwell time 📊⭐⭐⭐ | Hybrid infra, compromised accounts, insider threat detection 💡 | Detects novel attacks and credential abuse; continuous learning ⭐ |
| Threat Intelligence Integration and IOC Correlation | Medium 🔄🔄, feed ingestion and enrichment | Medium–High ⚡⚡, feed subscriptions, storage, curation | Rapid identification of known IOCs; faster MTTD 📊⭐⭐ | Known-malware detection, incident response, retrospective hunts 💡 | Fast, confident detection of known indicators; evidence for investigations ⭐ |
| Anomaly Detection via Log Pattern Analysis | Medium 🔄🔄, baselining and tuning | Medium ⚡⚡, log collection, parsing, retention | Detects novel attacks and misconfigurations; explainable alerts 📊⭐⭐ | Broad log sources, config drift detection, observability use cases 💡 | Low overhead; works across diverse log sources; seasonal adjustment possible ⭐ |
| Hunt via MITRE ATT&CK Framework and Tactic Mapping | High 🔄🔄🔄, expertise and mapping maintenance | Medium ⚡⚡, analyst time, mapping tools | Structured, repeatable hunts; improved detection coverage 📊⭐⭐⭐ | Threat hunting programs, gap analysis, SOC maturity building 💡 | Standardized methodology; visibility into attack chains and predictions ⭐ |
| Network Traffic Analysis (NTA) and DNS/NetFlow Hunting | Medium–High 🔄🔄🔄, network taps and flow tooling | Medium ⚡⚡, flow storage, sensors, aggregation | Detects C2, exfiltration, lateral movement missed by hosts 📊⭐⭐ | Encrypted traffic analysis, C2 detection, segmented networks 💡 | High detection value with lightweight collection; works without agents ⭐ |
| File Integrity Monitoring (FIM) and Registry Monitoring | Medium 🔄🔄, agent rollout and tuning | Medium ⚡⚡, agents, storage for change history | Early tamper detection and forensic evidence generation 📊⭐⭐ | Critical servers, configuration tracking, compliance audits 💡 | Early persistence/rootkit detection; low FP rate when tuned ⭐ |
| Process Execution and Command-Line Analysis | Medium 🔄🔄, endpoint agents and rule creation | Low–Medium ⚡⚡, endpoint telemetry (Sysmon/EDR) | Detects suspicious process chains and LOLBin abuse 📊⭐⭐ | Endpoint-focused hunts, privilege escalation, malware behavior analysis 💡 | Effective against living‑off‑the‑land techniques; low runtime overhead ⭐ |
| Credential Access and Authentication Anomaly Hunting | Medium 🔄🔄, centralizing diverse auth logs | Medium ⚡⚡, auth log collection, baselining | Early detection of compromised accounts; reduce lateral movement 📊⭐⭐⭐ | Identity protection, MFA validation, impossible‑travel detection 💡 | High-value early warning for account compromise; actionable lockdowns ⭐ |
| Data Exfiltration Detection and DLP-Based Hunting | High 🔄🔄🔄, content inspection and baselines | High ⚡⚡⚡, DLP tooling, content analysis, storage | Prevents data breaches; detects insider exfiltration attempts 📊⭐⭐ | Data protection (GDPR/HIPAA), insider threat, pre‑breach detection 💡 | Preventive containment and compliance support; content-aware detection ⭐ |
| Vulnerability Assessment, Patch Gap, and Malware/EDR Hunting | High 🔄🔄🔄, scanning + EDR integration | High ⚡⚡⚡, scanners, EDR agents, telemetry storage | Prioritized risk reduction; detection of active exploitation 📊⭐⭐⭐ | Patch management, incident response, reducing attack surface 💡 | Prevents exploitation; deep forensic and live‑response capabilities ⭐ |
Operationalize Your Threat Hunting Program with a Unified Platform
Monday, 08:15. The SOC is looking at three separate alerts. An impossible-travel sign-in, a PowerShell child process on an executive laptop, and a surge of DNS requests to low-reputation domains from a build server. In a fragmented stack, these remain separate tickets. In an operational hunting program, they turn into one hypothesis to test, a defined set of telemetry to query, and a response path the team can follow without spending half the shift switching tools.
This highlights the distinction between performing hunts and operationalizing threat hunting. Advanced teams treat every technique in this guide as a repeatable process. Start with a hypothesis aligned to the threat model. Confirm that telemetry is both available and normalized. Run saved queries on the appropriate data set. Incorporate enrichment and triage actions within SOAR. If the pattern consistently delivers value, convert it into a production detection, including documented tuning notes for the SIEM or XDR.
The platform matters because correlation is the difficult part. UEBA requires identity, endpoint, and cloud context in one place. MITRE ATT&CK-based hunts require process trees, authentication logs, DNS, NetFlow, and control-plane activity mapped to common fields. Exfiltration hunts require DLP events aligned with user activity, asset criticality, and outbound network volume. If those data sources sit in separate consoles with separate schemas, the hunt slows down and analyst confidence falls.
Comprehensive coverage outweighs ingenuity.
A poor process-creation feed will undermine command-line hunting regardless of how strong the query is. Insufficient DNS retention will hamper command-and-control hunts. Cloud audit logs lacking identity context will leave role abuse and API misuse only partly explained. Build the ingestion layer first, normalize the most important fields, and suppress clear noise before it overwhelms the queue. In practice, I would prefer to give analysts fewer data sources with consistent timestamps, hostnames, user IDs, and asset tags than a larger volume of raw logs they cannot correlate rapidly.
The hunt design should dictate automation, rather than automation dictating the hunt. Effective SOAR playbooks take on the repetitive tasks: add HR and IAM context to users, retrieve parent-child process lineage from EDR, compare domains with threat intel, capture a host snapshot, create the case, and prepare containment choices. Retain approval gates for actions that cause disruption, including account suspension, isolating a host on shared systems, or blocking domains critical to the business. For quick, low-risk steps with a clear evidence threshold, automate them, such as appending enrichment, preserving volatile data, or revoking one risky session token.
A single platform is valuable because programs often get stuck at the transition among hunting, detection, and response. Unified Security Stack brings together SIEM, SOAR, and XDR capabilities while ingesting telemetry from cloud services, endpoints, network devices, APIs, Syslog, agents, and NetFlow. That has real operational value. A hunter can try an IOC correlation hypothesis, shift into endpoint evidence, confirm exposed assets with vulnerability data, and add a response playbook without recreating the process in disconnected tools. Capabilities like access rights auditing, file tracking, endpoint protection, dark web monitoring, and automated playbooks also assist teams in expanding from individual findings toward wider risk reduction.
The pragmatic methodology is straightforward. Choose one or two techniques from this article that align with your environment and the attack paths currently active. Record the hunting hypothesis prior to accessing the console. Specify the necessary telemetry, query logic, anticipated false positives, and enrichment procedures. Implement a SOAR playbook for high-confidence results. Subsequently, evaluate the outcomes after one week: identify what generated signal, what introduced noise, what telemetry was absent, and what should be established as a permanent rule in the SIEM or XDR.
That cycle of review is how programs advance. Analysts become faster. Detections become cleaner. Coverage expands without introducing chaos.
If you need a unified way to run these hunts, correlate results, and automate response, Unified Security Stack is designed precisely for that task. It consolidates SIEM, SOAR, XDR, compliance workflows, IOC correlation, log management, vulnerability scanning, and endpoint visibility in one open-source platform, allowing SOC teams to hunt more quickly, refine detections with reduced noise, and advance from hypothesis to containment without linking a dozen distinct tools.